Main Trick
\[ p(c) = \frac{1}{\sqrt{2\pi\alpha_1}} \exp\left(-\frac{1}{2\alpha_1}c^2\right) \]
Can compute \(m\) given \(c\). \[m = \frac{y_1 - c}{x}\]
Section 1.2.3 (pg 21–24) of Bishop (2006)
Sections 3.1-3.4 (pg 95-117) of Rogers and Girolami (2011)
Section 1.2.6 (start from just past eq 1.64 pg 30-32) of Bishop (2006)
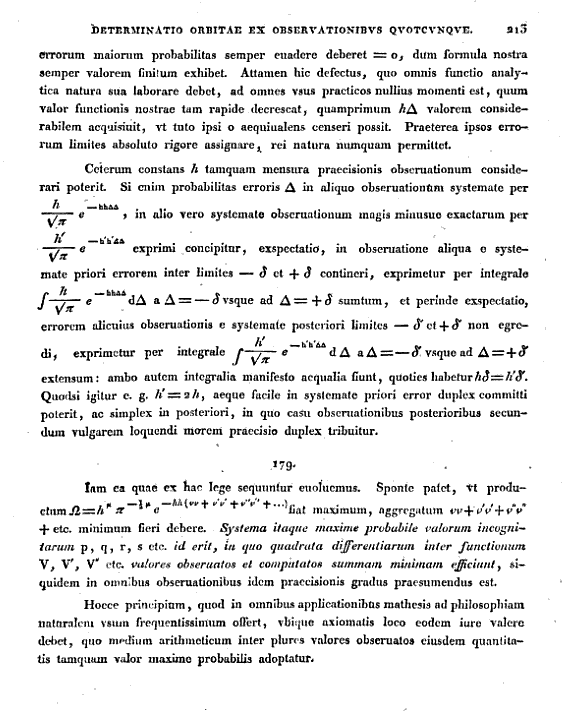
… It is clear, that for the product \(\Omega = h^\mu \pi^{-\frac{1}{2}\mu} e^{-hh(vv + v^\prime v^\prime + v^{\prime\prime} v^{\prime\prime} + \dots)}\) to be maximised the sum \(vv + v ^\prime v^\prime + v^{\prime\prime} v^{\prime\prime} + \text{etc}.\) ought to be minimized. Therefore, the most probable values of the unknown quantities \(p , q, r , s \text{etc}.\), should be that in which the sum of the squares of the differences between the functions \(V, V^\prime, V^{\prime\prime} \text{etc}\), and the observed values is minimized, for all observations of the same degree of precision is presumed.
Bayesian inference requires a prior on the parameters.
The prior represents your belief before you see the data of the likely value of the parameters.
For linear regression, consider a Gaussian prior on the intercept:
\[c \sim \mathscr{N}\left(0,\alpha_1\right)\]
\[ p(c) = \frac{1}{\sqrt{2\pi\alpha_1}} \exp\left(-\frac{1}{2\alpha_1}c^2\right) \]
\[ p(c| \mathbf{ y}, \mathbf{ x}, m, \sigma^2) = \frac{p(\mathbf{ y}|\mathbf{ x}, c, m, \sigma^2)p(c)}{p(\mathbf{ y}|\mathbf{ x}, m, \sigma^2)} \]
\[ p(c| \mathbf{ y}, \mathbf{ x}, m, \sigma^2) = \frac{p(\mathbf{ y}|\mathbf{ x}, c, m, \sigma^2)p(c)}{\int p(\mathbf{ y}|\mathbf{ x}, c, m, \sigma^2)p(c) \text{d} c} \]
\[ p(c| \mathbf{ y}, \mathbf{ x}, m, \sigma^2) \propto p(\mathbf{ y}|\mathbf{ x}, c, m, \sigma^2)p(c) \]
\[ \log p(c | \mathbf{ y}, \mathbf{ x}, m, \sigma^2) =-\frac{1}{2\sigma^2} \sum_{i=1}^n(y_i-c \\ & - mx_i)^2-\frac{1}{2\alpha_1} c^2 + \text{const}\]
\[ \log p(c | \mathbf{ y}, \mathbf{ x}, m, \sigma^2) = -\frac{1}{2\tau^2}(c - \mu)^2 +\text{const} \] \[ \tau^2 = \left(n\sigma^{-2} +\alpha_1^{-1}\right)^{-1} \] \[\mu = \frac{\tau^2}{\sigma^2} \sum_{i=1}^n(y_i-mx_i)\]
We assume height and weight are independent.
\[ p(w, h) = p(w)p(h). \]
displaycode{nu.display_plots(‘independent_height_weight{fig:0>3}.svg,’ directory=‘./ml,’ fig=IntSlider(0, 0, 7, 1))}
\[ p(w, h) = p(w)p(h) \]
\[ p(w, h) = \frac{1}{\sqrt{2\pi\sigma_1^22\pi\sigma_2^2}} \exp\left(-\frac{1}{2}\left(\begin{bmatrix}w \\ h\end{bmatrix} - \begin{bmatrix}\mu_1 \\ \mu_2\end{bmatrix}\right)^\top\begin{bmatrix}\sigma_1^2& 0\\0&\sigma_2^2\end{bmatrix}^{-1}\left(\begin{bmatrix}w \\ h\end{bmatrix} - \begin{bmatrix}\mu_1 \\ \mu_2\end{bmatrix}\right)\right) \]
\[ p(\mathbf{ y}) = \frac{1}{\det{2\pi \mathbf{D}}^{\frac{1}{2}}} \exp\left(-\frac{1}{2}(\mathbf{ y}- \boldsymbol{ \mu})^\top\mathbf{D}^{-1}(\mathbf{ y}- \boldsymbol{ \mu})\right) \]
\[ p(\mathbf{ y}) = \frac{1}{\det{2\pi\mathbf{D}}^{\frac{1}{2}}} \exp\left(-\frac{1}{2}(\mathbf{ y}- \boldsymbol{ \mu})^\top\mathbf{D}^{-1}(\mathbf{ y}- \boldsymbol{ \mu})\right) \]
\[ p(\mathbf{ y}) = \frac{1}{\det{2\pi\mathbf{D}}^{\frac{1}{2}}} \exp\left(-\frac{1}{2}(\mathbf{R}^\top\mathbf{ y}- \mathbf{R}^\top\boldsymbol{ \mu})^\top\mathbf{D}^{-1}(\mathbf{R}^\top\mathbf{ y}- \mathbf{R}^\top\boldsymbol{ \mu})\right) \]
\[ p(\mathbf{ y}) = \frac{1}{\det{2\pi\mathbf{D}}^{\frac{1}{2}}} \exp\left(-\frac{1}{2}(\mathbf{ y}- \boldsymbol{ \mu})^\top\mathbf{R}\mathbf{D}^{-1}\mathbf{R}^\top(\mathbf{ y}- \boldsymbol{ \mu})\right) \]
\[ \mathbf{C}^{-1} = \mathbf{R}\mathbf{D}^{-1} \mathbf{R}^\top \]
\[ p(\mathbf{ y}) = \frac{1}{\det{2\pi\mathbf{C}}^{\frac{1}{2}}} \exp\left(-\frac{1}{2}(\mathbf{ y}- \boldsymbol{ \mu})^\top\mathbf{C}^{-1} (\mathbf{ y}- \boldsymbol{ \mu})\right) \] \[ \mathbf{C}= \mathbf{R}\mathbf{D} \mathbf{R}^\top \]
Let’s assume that the prior density is given by a zero mean Gaussian, which is independent across each of the parameters, \[ \mathbf{ w}\sim \mathscr{N}\left(\mathbf{0},\alpha \mathbf{I}\right) \] In other words, we are assuming, for the prior, that each element of the parameters vector, \(w_i\), was drawn from a Gaussian density as follows \[ w_i \sim \mathscr{N}\left(0,\alpha\right) \] Let’s start by assigning the parameter of the prior distribution, which is the variance of the prior distribution, \(\alpha\).
Multivariate Gaussians: Section 2.3 up to top of pg 85 of Bishop (2006)
Section 3.3 up to 159 (pg 152–159) of Bishop (2006)
Use Bayesian approach on olympics data with polynomials.
Choose a prior \(\mathbf{ w}\sim \mathscr{N}\left(\mathbf{0},\alpha \mathbf{I}\right)\) with \(\alpha = 1\).
Choose noise variance \(\sigma^2 = 0.01\)
\[ \mathbf{ y}= \boldsymbol{ \Phi}\mathbf{ w}+ \boldsymbol{ \epsilon} \]
K = degree + 1
z_vec = np.random.normal(size=K)
w_sample = z_vec*np.sqrt(alpha)
f_sample = Phi_pred@w_sample
\[ \mathbf{ f}_s = \boldsymbol{ \Phi}\mathbf{ w}_s. \]
for i in range(num_samples):
    z_vec = np.random.normal(size=K)
    w_sample = z_vec*np.sqrt(alpha)
    f_sample = np.dot(Phi_pred,w_sample)
_ = ax.plot(x_pred.flatten(), f_sample.flatten(), linewidth=2)\[ p(\mathbf{ w}| \mathbf{ y}, \mathbf{ x}, \sigma^2) = \mathscr{N}\left(\mathbf{ w}|\boldsymbol{ \mu}_w,\mathbf{C}_w\right) \] with \[ \mathbf{C}_w= \left(\sigma^{-2}\boldsymbol{ \Phi}^\top \boldsymbol{ \Phi}+ \alpha^{-1}\mathbf{I}\right)^{-1} \] and \[ \boldsymbol{ \mu}_w= \mathbf{C}_w\sigma^{-2}\boldsymbol{ \Phi}^\top \mathbf{ y} \]
Image from Wikimedia Commons
\[ f_i = \boldsymbol{ \phi}_i^\top \mathbf{ w} \]
\[ f_i = \sum_{j=1}^K w_j \phi_{i, j} \]
\[ \left\langle\mathbf{ f}\right\rangle_{\mathscr{N}\left(\mathbf{ w}|\boldsymbol{ \mu},\mathbf{C}\right)} = \int \mathbf{ f} \mathscr{N}\left(\mathbf{ w}|\boldsymbol{ \mu},\mathbf{C}\right) \text{d}\mathbf{ w}= \int \boldsymbol{ \Phi}\mathbf{ w} \mathscr{N}\left(\mathbf{ w}|\boldsymbol{ \mu},\mathbf{C}\right) \text{d}\mathbf{ w}= \boldsymbol{ \Phi}\int \mathbf{ w} \mathscr{N}\left(\mathbf{ w}|\boldsymbol{ \mu},\mathbf{C}\right) \text{d}\mathbf{ w}= \boldsymbol{ \Phi}\boldsymbol{ \mu} \]
\[ \left\langle\mathbf{ f}\right\rangle_{\mathscr{N}\left(\mathbf{ w}|\mathbf{0},\alpha\mathbf{I}\right)} = \mathbf{0} \]
\[ \text{cov}\left(\mathbf{ f}\right)_{\mathscr{N}\left(\mathbf{ w}|\boldsymbol{ \mu},\mathbf{C}\right)} = \left\langle\mathbf{ f}\mathbf{ f}^\top\right\rangle_{\mathscr{N}\left(\mathbf{ w}|\boldsymbol{ \mu},\mathbf{C}\right)} - \left\langle\mathbf{ f}\right\rangle_{\mathscr{N}\left(\mathbf{ w}|\boldsymbol{ \mu},\mathbf{C}\right)}\left\langle\mathbf{ f}\right\rangle_{\mathscr{N}\left(\mathbf{ w}|\boldsymbol{ \mu},\mathbf{C}\right)}^\top \]
\[ \text{cov}\left(\mathbf{ f}\right)_{\mathscr{N}\left(\mathbf{ w}|\boldsymbol{ \mu},\mathbf{C}\right)} = \left\langle\mathbf{ f}\mathbf{ f}^\top\right\rangle_{\mathscr{N}\left(\mathbf{ w}|\boldsymbol{ \mu},\mathbf{C}\right)} - \boldsymbol{ \Phi}\boldsymbol{ \mu}\boldsymbol{ \mu}^\top \boldsymbol{ \Phi}^\top \]
\[ \text{cov}\left(\mathbf{ f}\right)_{\mathscr{N}\left(\mathbf{ w}|\boldsymbol{ \mu},\mathbf{C}\right)} = \left\langle\boldsymbol{ \Phi}\mathbf{ w}\mathbf{ w}^\top \boldsymbol{ \Phi}^\top\right\rangle_{\mathscr{N}\left(\mathbf{ w}|\boldsymbol{ \mu},\mathbf{C}\right)} - \boldsymbol{ \Phi}\boldsymbol{ \mu}\boldsymbol{ \mu}^\top \boldsymbol{ \Phi}^\top \] \[ \text{cov}\left(\mathbf{ f}\right)_{\mathscr{N}\left(\mathbf{ w}|\boldsymbol{ \mu},\mathbf{C}\right)} = \boldsymbol{ \Phi}\left\langle\mathbf{ w}\mathbf{ w}^\top\right\rangle_{\mathscr{N}\left(\mathbf{ w}|\boldsymbol{ \mu},\mathbf{C}\right)} \boldsymbol{ \Phi}^\top - \boldsymbol{ \Phi}\boldsymbol{ \mu}\boldsymbol{ \mu}^\top\boldsymbol{ \Phi}^\top \] Which is dependent on the second moment of the Gaussian, \[ \left\langle\mathbf{ w}\mathbf{ w}^\top\right\rangle_{\mathscr{N}\left(\mathbf{ w}|\boldsymbol{ \mu},\mathbf{C}\right)} = \mathbf{C}+ \boldsymbol{ \mu}\boldsymbol{ \mu}^\top \]
\[ \text{cov}\left(\mathbf{ f}\right)_{\mathscr{N}\left(\mathbf{ w}|\boldsymbol{ \mu},\mathbf{C}\right)} = \boldsymbol{ \Phi}\mathbf{C}\boldsymbol{ \Phi}^\top \] so in the case of the prior distribution, where we have \(\mathbf{C}= \alpha \mathbf{I}\) we can write \[ \text{cov}\left(\mathbf{ f}\right)_{\mathscr{N}\left(\mathbf{ w}|\mathbf{0},\alpha \mathbf{I}\right)} = \alpha \boldsymbol{ \Phi}\boldsymbol{ \Phi}^\top \]
\[ \mathbf{ y}= \mathbf{ f}+ \boldsymbol{ \epsilon} \]
\[ \mathbf{ f}\sim \mathscr{N}\left(\mathbf{0},\alpha\boldsymbol{ \Phi}\boldsymbol{ \Phi}^\top\right) \]
\[ p(\mathbf{ y}) = \mathscr{N}\left(\mathbf{ y}|\mathbf{0},\alpha \boldsymbol{ \Phi}\boldsymbol{ \Phi}^\top + \sigma^2\mathbf{I}\right) \]
\[ p(\mathbf{ y}|\mathbf{X}, \sigma^2, \alpha) = \frac{1}{(2\pi)^\frac{n}{2}\left|\mathbf{K}\right|^\frac{1}{2}} \exp\left(-\frac{1}{2} \mathbf{ y}^\top \mathbf{K}^{-1} \mathbf{ y}\right) \] \[ \mathbf{K}= \alpha \boldsymbol{ \Phi}\boldsymbol{ \Phi}^\top + \sigma^2 \mathbf{I} \]
\[ \mathbf{ f}= \boldsymbol{ \Phi}\mathbf{ w} \]
\[ \text{cov}\left(\mathbf{ f}\right)_{\mathscr{N}\left(\mathbf{ w}|\boldsymbol{ \mu}_w,\mathbf{C}_w\right)} = \boldsymbol{ \Phi}\mathbf{C}_w \boldsymbol{ \Phi}^\top \]
Section 3.7–3.8 (pg 122–133) of Rogers and Girolami (2011)
Section 3.4 (pg 161–165) of Bishop (2006)
company: Trent AI
book: The Atomic Human
twitter: @lawrennd
newspaper: Guardian Profile Page
blog posts:
