Linear Algebra and Linear Regression
Review
- Last time: Looked at objective functions for movie recommendation.
- Minimized sum of squares objective by steepest descent and stochastic gradients.
- This time: explore least squares for regression.
Regression Examples
- Predict a real value, \(y_i\) given some inputs \(\mathbf{ x}_i\).
- Predict quality of meat given spectral measurements (Tecator data).
- Radiocarbon dating, the C14 calibration curve: predict age given quantity of C14 isotope.
- Predict quality of different Go or Backgammon moves given expert rated training data.
Olympic Marathon Data
- Gold medal times for Olympic Marathon since 1896.
- Marathons before 1924 didn’t have a standardized distance.
- Present results using pace per km.
- In 1904 Marathon was badly organized leading to very slow times.
Image from Wikimedia Commons

Olympic Marathon Data
What is Machine Learning?
What is Machine Learning?
\[ \text{data} + \text{model} \stackrel{\text{compute}}{\rightarrow} \text{prediction}\]
- data : observations, could be actively or passively acquired (meta-data).
- model : assumptions, based on previous experience (other data! transfer learning etc), or beliefs about the regularities of the universe. Inductive bias.
- prediction : an action to be taken or a categorization or a quality score.
- Royal Society Report: Machine Learning: Power and Promise of Computers that Learn by Example
What is Machine Learning?
\[\text{data} + \text{model} \stackrel{\text{compute}}{\rightarrow} \text{prediction}\]
- To combine data with a model need:
- a prediction function \(f(\cdot)\) includes our beliefs about the regularities of the universe
- an objective function \(E(\cdot)\) defines the cost of misprediction.
Sum of Squares Error
Regression: Linear Relationship
\[y_i = m x_i + c\]
\(y_i\) : winning pace.
\(x_i\) : year of Olympics.
\(m\) : rate of improvement over time.
\(c\) : winning pace at year 0.
Overdetermined System
\(y= mx+ c\)
point 1: \(x= 1\), \(y=3\) \[ 3 = m + c \]
point 2: \(x= 3\), \(y=1\) \[ 1 = 3m + c \]
point 3: \(x= 2\), \(y=2.5\) \[ 2.5 = 2m + c \]
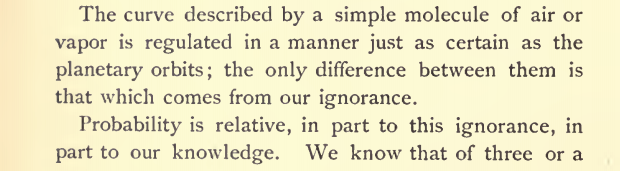
Pierre-Simon Laplace


Laplace’s Gremlin

Latent Variables
\(y= mx+ c + \epsilon\)
point 1: \(x= 1\), \(y=3\) \[ 3 = m + c + \epsilon_1 \]
point 2: \(x= 3\), \(y=1\) \[ 1 = 3m + c + \epsilon_2 \]
point 3: \(x= 2\), \(y=2.5\) \[ 2.5 = 2m + c + \epsilon_3 \]
A Probabilistic Process
Set the mean of Gaussian to be a function. \[ p\left(y_i|x_i\right)=\frac{1}{\sqrt{2\pi\sigma^2}}\exp \left(-\frac{\left(y_i-f\left(x_i\right)\right)^{2}}{2\sigma^2}\right). \]
This gives us a ‘noisy function.’
This is known as a stochastic process.
The Gaussian Density
- Perhaps the most common probability density.
\[\begin{align} p(y| \mu, \sigma^2) & = \frac{1}{\sqrt{2\pi\sigma^2}}\exp\left(-\frac{(y- \mu)^2}{2\sigma^2}\right)\\& \buildrel\triangle\over = \mathscr{N}\left(y|\mu,\sigma^2\right) \end{align}\]
Gaussian Density
Gaussian Density
Two Important Gaussian Properties
Sum of Gaussians
\[y_i \sim \mathscr{N}\left(\mu_i,\sigma_i^2\right)\]
\[ \sum_{i=1}^{n} y_i \sim \mathscr{N}\left(\sum_{i=1}^n\mu_i,\sum_{i=1}^n\sigma_i^2\right) \]
(Aside: As sum increases, sum of non-Gaussian, finite variance variables is also Gaussian because of central limit theorem.)
Scaling a Gaussian
\[y\sim \mathscr{N}\left(\mu,\sigma^2\right)\]
\[wy\sim \mathscr{N}\left(w\mu,w^2 \sigma^2\right).\]
Laplace’s Idea
A Probabilistic Process
Set the mean of Gaussian to be a function.
\[p\left(y_i|x_i\right)=\frac{1}{\sqrt{2\pi\sigma^2}}\exp\left(-\frac{\left(y_i-f\left(x_i\right)\right)^{2}}{2\sigma^2}\right).\]
This gives us a ‘noisy function.’
This is known as a stochastic process.
Height as a Function of Weight
In the standard Gaussian, parameterized by mean and variance, make the mean a linear function of an input.
This leads to a regression model. \[ \begin{align*} y_i=&f\left(x_i\right)+\epsilon_i,\\ \epsilon_i \sim & \mathscr{N}\left(0,\sigma^2\right). \end{align*} \]
Assume \(y_i\) is height and \(x_i\) is weight.
Data Point Likelihood
Likelihood of an individual data point \[ p\left(y_i|x_i,m,c\right)=\frac{1}{\sqrt{2\pi \sigma^2}}\exp\left(-\frac{\left(y_i-mx_i-c\right)^{2}}{2\sigma^2}\right). \] Parameters are gradient, \(m\), offset, \(c\) of the function and noise variance \(\sigma^2\).
Data Set Likelihood
If the noise, \(\epsilon_i\) is sampled independently for each data point. Each data point is independent (given \(m\) and \(c\)). For independent variables: \[ p(\mathbf{ y}) = \prod_{i=1}^np(y_i) \] \[ p(\mathbf{ y}|\mathbf{ x}, m, c) = \prod_{i=1}^np(y_i|x_i, m, c) \]
For Gaussian
i.i.d. assumption \[ p(\mathbf{ y}|\mathbf{ x}, m, c) = \prod_{i=1}^n\frac{1}{\sqrt{2\pi \sigma^2}}\exp \left(-\frac{\left(y_i- mx_i-c\right)^{2}}{2\sigma^2}\right). \]
\[ p(\mathbf{ y}|\mathbf{ x}, m, c) = \frac{1}{\left(2\pi \sigma^2\right)^{\frac{n}{2}}}\exp\left(-\frac{\sum_{i=1}^n\left(y_i-mx_i-c\right)^{2}}{2\sigma^2}\right). \]
Log Likelihood Function
- Normally work with the log likelihood: \[\begin{aligned} L(m,c,\sigma^{2})= & -\frac{n}{2}\log 2\pi -\frac{n}{2}\log \sigma^2 \\& -\sum_{i=1}^{n}\frac{\left(y_i-mx_i-c\right)^{2}}{2\sigma^2}. \end{aligned}\]
Consistency of Maximum Likelihood
- If data was really generated according to probability we specified.
- Correct parameters will be recovered in limit as \(n\rightarrow \infty\).
Consistency of Maximum Likelihood
- This can be proven through sample based approximations (law of large numbers) of “KL divergences.”
- Mainstay of classical statistics (Wasserman, 2003).
Probabilistic Interpretation of Error Function
- Probabilistic Interpretation for Error Function is Negative Log Likelihood.
- Minimizing error function is equivalent to maximizing log likelihood.
Probabilistic Interpretation of Error Function
- Maximizing log likelihood is equivalent to maximizing the likelihood because \(\log\) is monotonic.
- Probabilistic interpretation: Minimizing error function is equivalent to maximum likelihood with respect to parameters.
Error Function
- Negative log likelihood leads to an error function \[\begin{aligned} E(m,c,\sigma^{2})= & \frac{n}{2}\log \sigma^2 \\& +\frac{1}{2\sigma^2}\sum _{i=1}^{n}\left(y_i-mx_i-c\right)^{2}.\end{aligned}\]
- Learning by minimising error function.
Sum of Squares Error
- Ignoring terms which don’t depend on \(m\) and \(c\) gives \[E(m, c) \propto \sum_{i=1}^n(y_i - f(x_i))^2\] where \(f(x_i) = mx_i + c\).
Sum of Squares Error
- This is recognised as the sum of squares error function.
- Commonly used and is closely associated with the Gaussian likelihood.
Reminder
- Two functions involved:
- Prediction function: \(f(x_i)\)
- Error, or Objective function: \(E(m, c)\)
- Error function depends on parameters through prediction function.
Mathematical Interpretation
- What is the mathematical interpretation?
- There is a cost function.
- It expresses mismatch between your prediction and reality. \[ E(m, c)=\sum_{i=1}^n\left(y_i - mx_i-c\right)^2 \]
- This is known as the sum of squares error.
Legendre
- Sum of squares error was first published by Legendre in 1805
- But Laplace had priority - he used it to recover the lost planet Ceres
- This led to a priority dispute between Legendre and Gauss
Legendre
Running Example: Olympic Marathons
Maximum Likelihood: Iterative Solution
\[ E(m, c) = \sum_{i=1}^n(y_i-mx_i-c)^2 \]
Coordinate Descent
Learning is Optimisation
- Learning is minimisation of the cost function.
- At the minima the gradient is zero.
- Coordinate descent, find gradient in each coordinate and set to zero. \[\frac{\text{d}E(c)}{\text{d}c} = -2\sum_{i=1}^n\left(y_i- m x_i - c \right)\] \[0 = -2\sum_{i=1}^n\left(y_i- mx_i - c \right)\]
Learning is Optimisation
- Fixed point equations \[0 = -2\sum_{i=1}^ny_i +2\sum_{i=1}^nm x_i +2n c\] \[c = \frac{\sum_{i=1}^n\left(y_i - mx_i\right)}{n}\]
Learning is Optimisation
- Learning is minimisation of the cost function.
- At the minima the gradient is zero.
- Coordinate descent, find gradient in each coordinate and set to zero. \[\frac{\text{d}E(m)}{\text{d}m} = -2\sum_{i=1}^nx_i\left(y_i- m x_i - c \right)\] \[0 = -2\sum_{i=1}^nx_i \left(y_i-m x_i - c \right)\]
Learning is Optimisation
- Fixed point equations \[0 = -2\sum_{i=1}^nx_iy_i+2\sum_{i=1}^nm x_i^2+2\sum_{i=1}^ncx_i\] \[m = \frac{\sum_{i=1}^n\left(y_i -c\right)x_i}{\sum_{i=1}^nx_i^2}\]
\[m^* = \frac{\sum_{i=1}^n(y_i - c)x_i}{\sum_{i=1}^nx_i^2}\]
Fixed Point Updates
\[ \begin{aligned} c^{*}=&\frac{\sum _{i=1}^{n}\left(y_i-m^{*}x_i\right)}{n},\\ m^{*}=&\frac{\sum _{i=1}^{n}x_i\left(y_i-c^{*}\right)}{\sum _{i=1}^{n}x_i^{2}},\\ \left.\sigma^2\right.^{*}=&\frac{\sum _{i=1}^{n}\left(y_i-m^{*}x_i-c^{*}\right)^{2}}{n} \end{aligned} \]
Coordiate Descent Algorithm
Important Concepts Not Covered
- Other optimization methods:
- Second order methods, conjugate gradient, quasi-Newton and Newton.
- Effective heuristics such as momentum.
- Local vs global solutions.
Multi-dimensional Inputs
- Multivariate functions involve more than one input.
- Height might be a function of weight and gender.
- There could be other contributory factors.
- Place these factors in a feature vector \(\mathbf{ x}_i\).
- Linear function is now defined as \[f(\mathbf{ x}_i) = \sum_{j=1}^p w_j x_{i, j} + c\]
Vector Notation
- Write in vector notation, \[f(\mathbf{ x}_i) = \mathbf{ w}^\top \mathbf{ x}_i + c\]
- Can absorb \(c\) into \(\mathbf{ w}\) by assuming extra input \(x_0\) which is always 1. \[f(\mathbf{ x}_i) = \mathbf{ w}^\top \mathbf{ x}_i\]
Objective Functions and Regression
- Classification: map feature to class label.
- Regression: map feature to real value
Regression
Our prediction function is \[f(x_i) = mx_i + c\]
Need an algorithm to fit it.
Least Squares
- Least squares: minimise an error.
\[E(m, c) = \sum_{i=1}^n(y_i - f(x_i))^2\]
Regression
Create an artifical data set.
true value for \(m\)
m_true = 1.4true value for \(c\)
c_true = -3.1
We can use these values to create our artificial data. The formula \[y_i = mx_i + c\] is translated to code as follows:
y = m_true*x+c_true
Plot of Data
We can now plot the artifical data we’ve created.
Plot of data
- Points lie exactly on a straight line
- Not very realistic
- Corrupt them with Gaussian ‘noise.’
Noise Corrupted Plot
Contour Plot of Error Function
Steepest Descent
- Minimise the sum of squares error function.
- E.g. gradient descent.
- Initialise with a guess for \(m\) and \(c\)
- update that guess by subtracting a portion of the gradient from the guess.
- Like walking down a hill in the steepest direction of the hill to get to the bottom.
Algorithm
- We start with a guess for \(m\) and \(c\).
m_star = 0.0
c_star = -5.0
Offset Gradient
- Gradient of the error wrt \(c\), \[ \frac{\text{d}E(m, c)}{\text{d} c} = -2\sum_{i=1}^n(y_i - mx_i - c) \]
Compute as
c_grad = -2*(y-m_star*x - c_star).sum()Slope Gradient
Gradient wrt \(m\) is similar \[ \frac{\text{d}E(m, c)}{\text{d} m} = -2\sum_{i=1}^nx_i(y_i - mx_i - c) \]
Compute as
which can be implemented in python (numpy) as
m_grad = -2*(x*(y-m_star*x - c_star)).sum()Update Equations
- Gradients with respect to \(m\) and \(c\).
- Can update our inital guesses for \(m\) and \(c\) using the gradient.
Update Equations
- We don’t want to just subtract the gradient from \(m\) and \(c\),
- We need to take a small step in the gradient direction.
- Otherwise we might overshoot the minimum.
Update Equations
- We want to follow the gradient to get to the minimum, the gradient changes all the time.
Move in Direction of Gradient
Update Equations
- The step size has already been introduced
- it’s known as the learning rate and is denoted by \(\eta\). \[ c_\text{new}\leftarrow c_{\text{old}} - \eta\frac{\text{d}E(m, c)}{\text{d}c} \]
Step Size
- gives us an update for our estimate of \(c\) and \[ m_\text{new} \leftarrow m_{\text{old}} - \eta\frac{\text{d}E(m, c)}{\text{d}m} \]
- Giving us an update for \(m\).
Update Code
- These updates can be coded as
learn_rate = 0.01
c_star = c_star - learn_rate*c_grad
m_star = m_star - learn_rate*m_grad
Iterating Updates
- Fit model by descending gradient.
Gradient Descent Algorithm
Stochastic Gradient Descent
- If \(n\) is small, gradient descent is fine.
- But sometimes (e.g. on the internet) \(n\) could be a billion.
- Stochastic gradient descent is more similar to perceptron.
- Look at gradient of one data point at a time rather than summing across all data points)
- This gives a stochastic estimate of gradient.
Stochastic Gradient Descent
- The real gradient with respect to \(m\) is given by \[ \frac{\text{d}E(m, c)}{\text{d} m} = -2\sum_{i=1}^nx_i(y_i - mx_i - c) \]
Decompose the Sum
but it has \(n\) terms in the sum. Substituting in the gradient we can see that the full update is of the form \[\begin{aligned} m_\text{new} \leftarrow m_\text{old} \\ & + 2\eta\left[x_1 (y_1 - m_\text{old}x_1 - c_\text{old}) \right. \\ & + (x_2 (y_2 - m_\text{old}x_2 - c_\text{old}) \\ & + \dots + (x_n (y_n - m_\text{old}x_n - c_\text{old})\right] \end{aligned}\]This could be split up into lots of individual updates \[m_1 \leftarrow m_\text{old} + 2\eta\left[x_1 (y_1 - m_\text{old}x_1 - c_\text{old})\right]\] \[m_2 \leftarrow m_1 + 2\eta\left[x_2 (y_2 - m_\text{old}x_2 - c_\text{old})\right]\] \[m_3 \leftarrow m_2 + 2\eta \left[\dots\right]\] \[m_n \leftarrow m_{n-1} + 2\eta\left[x_n (y_n - m_\text{old}x_n - c_\text{old})\right]\]
which would lead to the same final update.
Updating \(c\) and \(m\)
- In the sum we don’t change \(m\) and \(c\) we use for computing the gradient term at each update.
- In stochastic gradient descent we do change them.
- This means it’s not quite the same as steepest descent.
- But we can present each data point in a random order, like we did for the perceptron.
- This makes the algorithm suitable for large-scale data use
Stochastic Gradient Descent
- Since the data is presented in a random order we write \[ m_\text{new} = m_\text{old} + 2\eta\left[x_i (y_i - m_\text{old}x_i - c_\text{old})\right] \]
SGD for Linear Regression
Putting it all together in an algorithm, we can do stochastic gradient descent for our regression data.
Mini-Batch
- In practice use mini-batches.
- Instead of computing gradient of one example.
- Use a small batch of examples.
Reflection on Linear Regression and Supervised Learning
- Learning rate size
- Smaller data sets and variation in results
Log Likelihood for Multivariate Regression
The likelihood of a single data point is
\[p\left(y_i|x_i\right)=\frac{1}{\sqrt{2\pi\sigma^2}}\exp\left(-\frac{\left(y_i-\mathbf{ w}^{\top}\mathbf{ x}_i\right)^{2}}{2\sigma^2}\right).\]
Log Likelihood for Multivariate Regression
Leading to a log likelihood for the data set of
Error Function
And a corresponding error function of \[E(\mathbf{ w},\sigma^2)=\frac{n}{2}\log\sigma^2 + \frac{\sum_{i=1}^{n}\left(y_i-\mathbf{ w}^{\top}\mathbf{ x}_i\right)^{2}}{2\sigma^2}.\]
Quadratic Loss
\[ E(\mathbf{ w}) = \sum_{i=1}^n\left(y_i - f(\mathbf{ x}_i, \mathbf{ w})\right)^2 \]
Linear Model
\[ E(\mathbf{ w}) = \sum_{i=1}^n\left(y_i - \mathbf{ w}^\top \mathbf{ x}_i\right)^2 \]
Bracket Expansion
\[ \begin{align*} E(\mathbf{ w},\sigma^2) = & \frac{n}{2}\log \sigma^2 + \frac{1}{2\sigma^2}\sum _{i=1}^{n}y_i^{2}-\frac{1}{\sigma^2}\sum _{i=1}^{n}y_i\mathbf{ w}^{\top}\mathbf{ x}_i\\&+\frac{1}{2\sigma^2}\sum _{i=1}^{n}\mathbf{ w}^{\top}\mathbf{ x}_i\mathbf{ x}_i^{\top}\mathbf{ w} +\text{const}.\\ = & \frac{n}{2}\log \sigma^2 + \frac{1}{2\sigma^2}\sum _{i=1}^{n}y_i^{2}-\frac{1}{\sigma^2} \mathbf{ w}^\top\sum_{i=1}^{n}\mathbf{ x}_iy_i\\&+\frac{1}{2\sigma^2} \mathbf{ w}^{\top}\left[\sum _{i=1}^{n}\mathbf{ x}_i\mathbf{ x}_i^{\top}\right]\mathbf{ w}+\text{const}. \end{align*} \]
Design Matrix
\[ \mathbf{X} = \begin{bmatrix} \mathbf{ x}_1^\top \\\ \mathbf{ x}_2^\top \\\ \vdots \\\ \mathbf{ x}_n^\top \end{bmatrix} = \begin{bmatrix} 1 & x_1 \\\ 1 & x_2 \\\ \vdots & \vdots \\\ 1 & x_n \end{bmatrix} \]
Writing the Objective with Linear Algebra
\[ E(\mathbf{ w}) = \sum_{i=1}^n(y_i - f(\mathbf{ x}_i; \mathbf{ w}))^2, \]
\[ f(\mathbf{ x}_i; \mathbf{ w}) = \mathbf{ x}_i^\top \mathbf{ w}. \]
Stacking Vectors
\[ \mathbf{ f}= \begin{bmatrix}f_1\\f_2\\ \vdots \\ f_n\end{bmatrix}. \]
\[ E(\mathbf{ w}) = (\mathbf{ y}- \mathbf{ f})^\top(\mathbf{ y}- \mathbf{ f}) \]
\[ \mathbf{ f}= \mathbf{X}\mathbf{ w}. \]
\[ E(\mathbf{ w}) = (\mathbf{ y}- \mathbf{ f})^\top(\mathbf{ y}- \mathbf{ f}) \]
Objective Optimization
Multivariate Derivatives
- We will need some multivariate calculus.
- For now some simple multivariate differentiation: \[\frac{\text{d}{\mathbf{a}^{\top}}{\mathbf{ w}}}{\text{d}\mathbf{ w}}=\mathbf{a}\] and \[\frac{\mathbf{ w}^{\top}\mathbf{A}\mathbf{ w}}{\text{d}\mathbf{ w}}=\left(\mathbf{A}+\mathbf{A}^{\top}\right)\mathbf{ w}\] or if \(\mathbf{A}\) is symmetric (i.e. \(\mathbf{A}=\mathbf{A}^{\top}\)) \[\frac{\text{d}\mathbf{ w}^{\top}\mathbf{A}\mathbf{ w}}{\text{d}\mathbf{ w}}=2\mathbf{A}\mathbf{ w}.\]
Differentiate the Objective
\[ \frac{\partial L\left(\mathbf{ w},\sigma^2 \right)}{\partial \mathbf{ w}}=\frac{1}{\sigma^2} \sum _{i=1}^{n}\mathbf{ x}_i y_i-\frac{1}{\sigma^2} \left[\sum _{i=1}^{n}\mathbf{ x}_i\mathbf{ x}_i^{\top}\right]\mathbf{ w} \] Leading to \[ \mathbf{ w}^{*}=\left[\sum _{i=1}^{n}\mathbf{ x}_i\mathbf{ x}_i^{\top}\right]^{-1}\sum _{i=1}^{n}\mathbf{ x}_iy_i, \]
Differentiate the Objective
Rewrite in matrix notation: \[ \sum_{i=1}^{n}\mathbf{ x}_i\mathbf{ x}_i^\top = \mathbf{X}^\top \mathbf{X} \] \[ \sum_{i=1}^{n}\mathbf{ x}_iy_i = \mathbf{X}^\top \mathbf{ y} \]
Update Equation for Global Optimum
Update Equations
Solve the matrix equation for \(\mathbf{ w}\). \[\mathbf{X}^\top \mathbf{X}\mathbf{ w}= \mathbf{X}^\top \mathbf{ y}\]
The equation for \(\left.\sigma^2\right.^{*}\) may also be found \[\left.\sigma^2\right.^{{*}}=\frac{\sum_{i=1}^{n}\left(y_i-\left.\mathbf{ w}^{*}\right.^{\top}\mathbf{ x}_i\right)^{2}}{n}.\]
Movie Violence Data
- Data containing movie information (year, length, rating, genre, IMDB Rating).
- Try and predict what factors influence a movie’s violence
Multivariate Regression on Movie Violence Data
- Regress from features
Year,Body_Count,Length_MinutestoIMDB_Rating.
Residuals
Solution with QR Decomposition
\[ \mathbf{X}^\top \mathbf{X}\boldsymbol{\beta} = \mathbf{X}^\top \mathbf{ y} \] substitute \(\mathbf{X}= \mathbf{Q}\mathbf{R}\) \[ (\mathbf{Q}\mathbf{R})^\top (\mathbf{Q}\mathbf{R})\boldsymbol{\beta} = (\mathbf{Q}\mathbf{R})^\top \mathbf{ y} \] \[ \mathbf{R}^\top (\mathbf{Q}^\top \mathbf{Q}) \mathbf{R} \boldsymbol{\beta} = \mathbf{R}^\top \mathbf{Q}^\top \mathbf{ y} \]
\[ \mathbf{R}^\top \mathbf{R} \boldsymbol{\beta} = \mathbf{R}^\top \mathbf{Q}^\top \mathbf{ y} \] \[ \mathbf{R} \boldsymbol{\beta} = \mathbf{Q}^\top \mathbf{ y} \]
- More nummerically stable.
- Avoids the intermediate computation of \(\mathbf{X}^\top\mathbf{X}\).
Hessian Matrix
\[ \frac{\text{d}^2}{\text{d}\mathbf{ w}\text{d}\mathbf{ w}^\top} E(\mathbf{ w}) = 2\mathbf{X}^\top\mathbf{X}. \]
Eigendecomposition of Hessian
\[ \mathbf{A}\mathbf{u} = \lambda\mathbf{u} \]
\[ \mathbf{X}^\top\mathbf{X}\mathbf{u}_i = \lambda_i \mathbf{u}_i. \]
Thanks!
company: Trent AI
book: The Atomic Human
twitter: @lawrennd
newspaper: Guardian Profile Page
blog posts:
Further Reading
For fitting linear models: Section 1.1-1.2 of Rogers and Girolami (2011)
Section 1.2.5 up to equation 1.65 of Bishop (2006)
Section 1.3 for Matrix & Vector Review of Rogers and Girolami (2011)