Unsupervised Learning with Gaussian Processes
GPy: A Gaussian Process Framework in Python
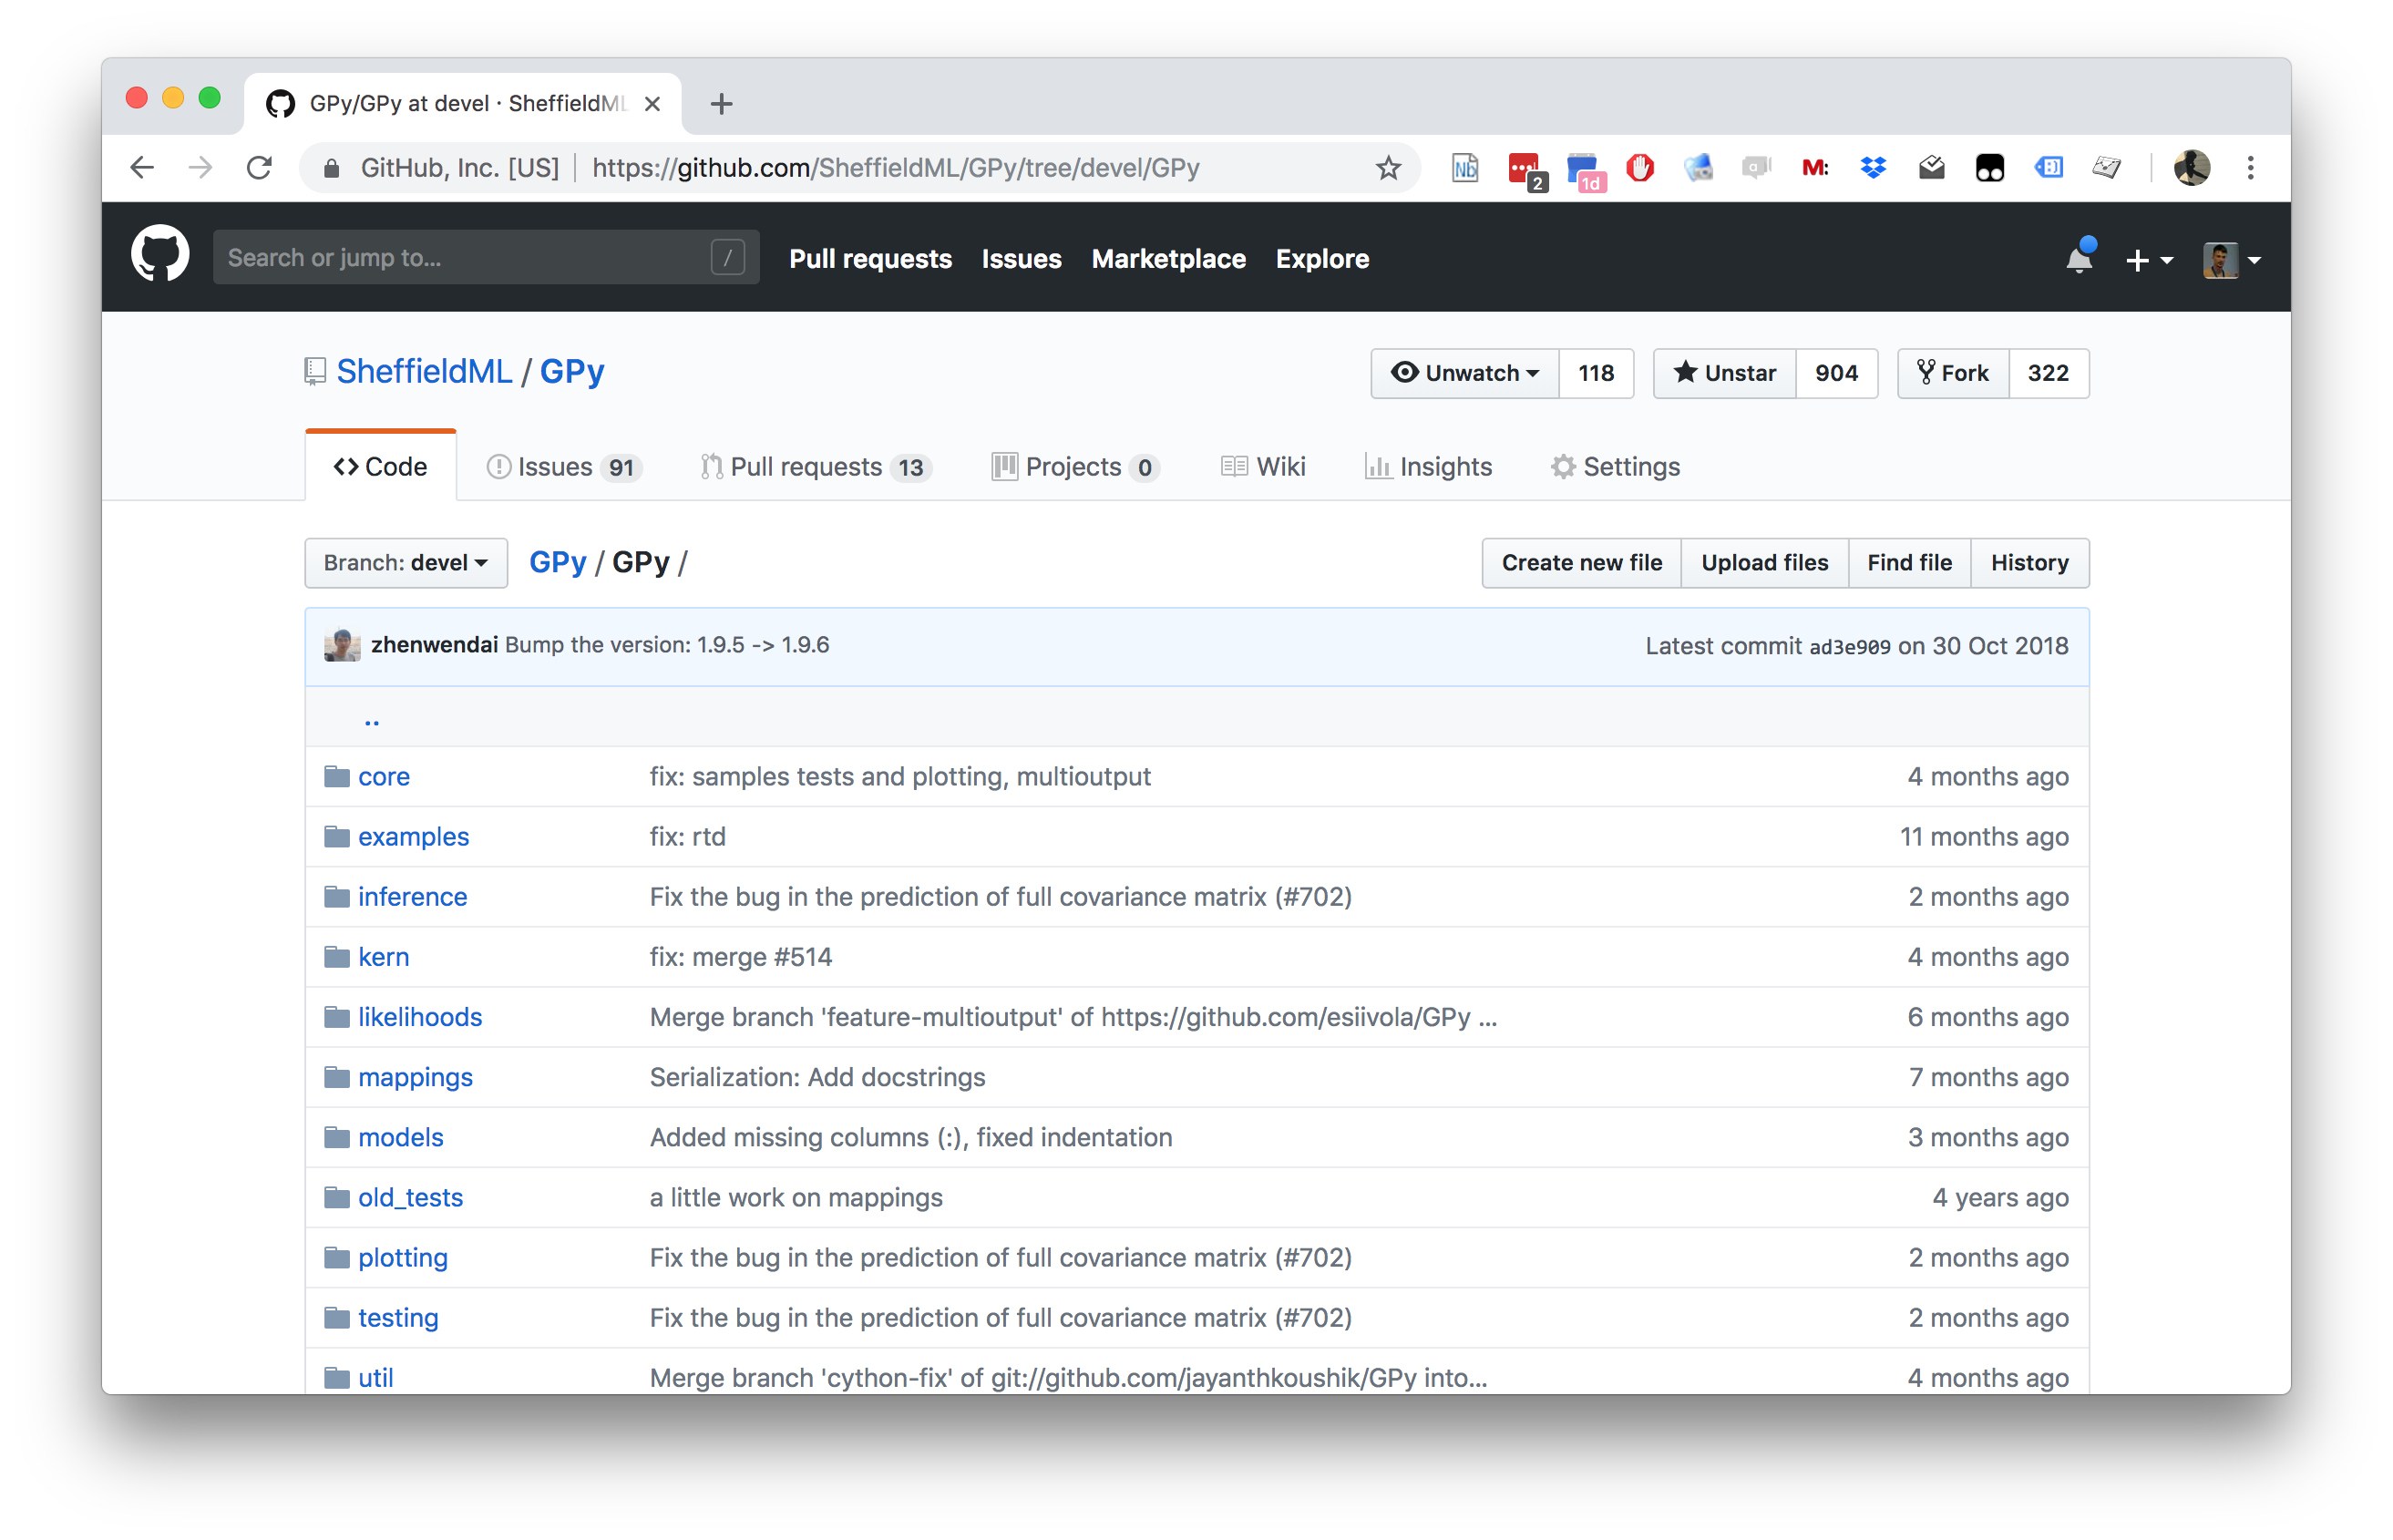
GPy: A Gaussian Process Framework in Python
- BSD Licensed software base.
- Wide availability of libraries, ‘modern’ scripting language.
- Allows us to set projects to undergraduates in Comp Sci that use GPs.
- Available through GitHub https://github.com/SheffieldML/GPy
- Reproducible Research with Jupyter Notebook.
Features
- Probabilistic-style programming (specify the model, not the algorithm).
- Non-Gaussian likelihoods.
- Multivariate outputs.
- Dimensionality reduction.
- Approximations for large data sets.
Probabilistic PCA
- Represent data, \(\mathbf{Y}\), with a lower dimensional set of latent variables \(\mathbf{Z}\).
- Assume a linear relationship of the form \[ \mathbf{ y}_{i,:}=\mathbf{W}\mathbf{ z}_{i,:}+\boldsymbol{ \epsilon}_{i,:}, \] where \[ \boldsymbol{ \epsilon}_{i,:} \sim \mathscr{N}\left(\mathbf{0},\sigma^2\mathbf{I}\right) \]
Probabilistic PCA
- PPCA defines a probabilistic model where:
- Data is generated from latent variables through linear transformation
- Gaussian noise is added to the transformed variables
- Latent variables have standard Gaussian prior
- Maximum likelihood recovers classical PCA
Graphical model representing probabilistic PCA
Posterior for Principal Component Analysis
\[ p(\mathbf{ z}_{i, :} | \mathbf{ y}_{i, :}) \]
\[ p(\mathbf{ z}_{i, :} | \mathbf{ y}_{i, :}) \propto p(\mathbf{ y}_{i, :}|\mathbf{W}, \mathbf{ z}_{i, :}, \sigma^2) p(\mathbf{ z}_{i, :}) \]
\[ \log p(\mathbf{ z}_{i, :} | \mathbf{ y}_{i, :}) = \log p(\mathbf{ y}_{i, :}|\mathbf{W}, \mathbf{ z}_{i, :}, \sigma^2) + \log p(\mathbf{ z}_{i, :}) + \text{const} \]
\[ \log p(\mathbf{ z}_{i, :} | \mathbf{ y}_{i, :}) = -\frac{1}{2\sigma^2} (\mathbf{ y}_{i, :} - \mathbf{W}\mathbf{ z}_{i, :})^\top(\mathbf{ y}_{i, :} - \mathbf{W}\mathbf{ z}_{i, :}) - \frac{1}{2} \mathbf{ z}_{i, :}^\top \mathbf{ z}_{i, :} + \text{const} \]
Scikit-learn implementation PCA
Oil Flow Data
Difficulty for Probabilistic Approaches
Propagate a probability distribution through a non-linear mapping.
Normalisation of distribution becomes intractable.
Difficulty for Probabilistic Approaches
Propagate a probability distribution through a non-linear mapping.
Normalisation of distribution becomes intractable.
Difficulty for Probabilistic Approaches
Propagate a probability distribution through a non-linear mapping.
Normalisation of distribution becomes intractable.
Getting Started and Downloading Data
Principal Component Analysis
- What is the right shape \(n\times d\) to use?
Gaussian Process Latent Variable Model
CMU Mocap Database
CMU Motion Capture GP-LVM
CMU Mocap Visualisation
Example: Latent Doodle Space
Example: Latent Doodle Space
Generalization with much less Data than Dimensions
Powerful uncertainly handling of GPs leads to surprising properties.
Non-linear models can be used where there are fewer data points than dimensions without overfitting.
Example: Continuous Character Control
- Graph diffusion prior for enforcing connectivity between motions. \[\log p(\mathbf{X}) = w_c \sum_{i,j} \log K_{ij}^d\] with the graph diffusion kernel \(\mathbf{K}^d\) obtain from \[K_{ij}^d = \exp(\beta \mathbf{H}) \qquad \text{with} \qquad \mathbf{H} = -\mathbf{T}^{-1/2} \mathbf{L} \mathbf{T}^{-1/2}\] the graph Laplacian, and \(\mathbf{T}\) is a diagonal matrix with \(T_{ii} = \sum_j w(\mathbf{ x}_i, \mathbf{ x}_j)\), \[L_{ij} = \begin{cases} \sum_k w(\mathbf{ x}_i,\mathbf{ x}_k) & \text{if $i=j$} \\ -w(\mathbf{ x}_i,\mathbf{ x}_j) &\text{otherwise.} \end{cases}\] and \(w(\mathbf{ x}_i,\mathbf{ x}_j) = || \mathbf{ x}_i - \mathbf{ x}_j||^{-p}\) measures similarity.
Character Control: Results
Data for Blastocyst Development in Mice: Single Cell TaqMan Arrays
Principal Component Analysis
PCA Result
GP-LVM on the Data
Blastocyst Data: Isomap
Blastocyst Data: Locally Linear Embedding
Thanks!
- company: Trent AI
- book: The Atomic Human
- twitter: @lawrennd
- The Atomic Human
- newspaper: Guardian Profile Page
- blog: http://inverseprobability.com